Stop Using Only RDS for Single-Cell Data — Give qs a Try!
Today, let's talk about a topic that sounds boring but can genuinely be a lifesaver — how to efficiently store your single-cell data. Single-cell datasets are getting massive. It's now routine to work with hundreds of thousands, even millions of cells. Even if your computer can handle the analysis, just saving the resulting Seurat object can take ages. And when you need to save multiple intermediate files? Not only is it time-consuming, but your storage space starts crying for help. Don't worry — today I'll share some handy tricks to make reading and writing single-cell data a breeze.
01
rds/RData
In R, the most common data storage formats are rds and RData. Both are R's native serialization formats: rds stores a single object, while RData can store multiple objects. The advantages are obvious: no compatibility issues, no restrictions on object types, no extra packages to install, and built-in compression support. Plus, you can open/import them directly in RStudio — no loading code needed. When sharing data with others (including for public datasets), these formats are the default choice.
# Assume obj is your Seurat object
# RDS save
saveRDS(obj,"/path/to/file/seurat_obj.rds")
# RDS load
obj <- readRDS("/path/to/file/seurat_obj.rds")

# Assume a and b are two arbitrary objects in the current environment
# RData save
save(a, b,"ab.RData")
# RData load
load("ab.RData")
# Or save the entire workspace
save.image("my_workspace.RData")
# Reload
load("my_workspace.RData")
02
qs/qs2
qs stands for Quick Serialization. It's an R package designed specifically for high-performance serialization and deserialization of R objects. In short, it does the same thing as saveRDS/readRDS, but much, much faster! Neither .qs nor .qs2 restricts the object type, so both work perfectly for storing Seurat objects. qs2 is the next-generation version of qs, with further performance optimizations and new features (also paving the way for qs's eventual retirement). Note that qs2 and qs use two different formats and are not cross-compatible. Usage is straightforward — both packages can be installed directly from CRAN:
# qs
install.packages("qs")
library(qs)

# Save
qsave(obj,"seurat_obj.qs")
# Load
obj <- qread("seurat_obj.qs")

# qs2 is very similar
install.packages("qs2")
# On Mac/Linux, if you need multi-threaded acceleration, compile from source
#remotes::install_cran("qs2", type = "source", configure.args = "--with-TBB --with-simd=AVX2")
# Apple Silicon Mac
#remotes::install_cran("qs2", type = "source", configure.args = "--with-TBB")
library(qs2)

# Save
qs_save(data,"myfile.qs2")
# Load
data <- qs_read("myfile.qs2")
qs2 can also convert to rds:
# qs2 to rds
qs_to_rds(input_file ="file.qs2", output_file ="file.rds")
So just how fast is qs/qs2? Let's run a simple benchmark. The test dataset contains 330,000 immune cells, and the test platform is an M4 Mac.
> obj
An object of class Seurat
17109 features across 333291 samples within 1 assay
Active assay: RNA (17109 features, 2000 variable features)
3 layers present: counts, data, scale.data
3 dimensional reductions calculated: pca, harmony, umap
This object occupies 18.7 GB of memory. 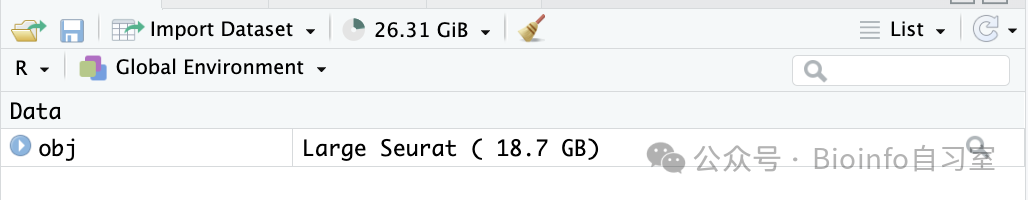 Save time comparison:
# rds — 371 seconds, over 6 minutes
> system.time(saveRDS(obj,"obj.rds"))
   user  system elapsed
367.920  2.701  371.013
# RData performs about the same
> system.time(save(obj, file ="obj.RData"))
   user  system elapsed
369.480  2.405  372.527
# qs — a full 10× faster!
> system.time(qsave(obj, file ="obj.qs"))
   user  system elapsed
34.139   3.742  37.999
# qs2 — even faster
> system.time(qs_save(obj, file ="obj.qs2"))
   user  system elapsed
24.707   1.686  26.480
Load time comparison:
# rds — loading is still reasonably fast
> system.time(readRDS("obj.rds"))
   user  system elapsed
17.810   1.241  19.051
# RData
> system.time(load("obj.RData"))
   user  system elapsed
17.905   1.190  19.090
# qs
> system.time(qread("obj.qs"))
   user  system elapsed
16.036   1.867  17.900
# qs2
> system.time(qs_read("obj.qs2"))
   user  system elapsed
7.396   0.973   8.368
Disk space comparison: 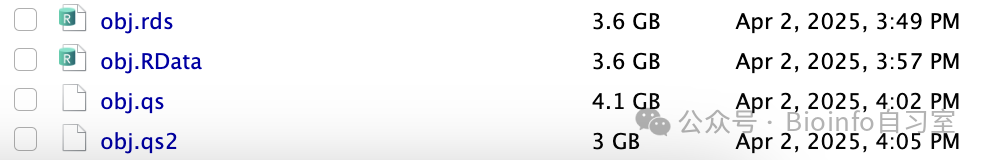
qs2 is in a league of its own — dramatically superior to rds and RData in both read/write speed and disk space usage.
03
Advanced Usage
If you want to push save speeds even further, you can leverage multi-threading. If you need smaller output files, you'll want to increase the compression level. However, higher compression inevitably slows down read/write speeds, so you'll need to find the right balance for your specific use case!
1. Adjust compression level:
# Fastest speed, but larger file size
qsave(obj,"fast_save.qs", preset ="fast")

# Smallest file size, but "slower" speed (default)
qsave(obj,"small_file.qs", preset ="high")

# qs2 uses the zstd library; adjust via compress_level (default is 3)
qs_save(obj,"fast_save.qs2", compress_level=1)  # Faster, less compression
qs_save(obj,"small_file.qs2", compress_level=5) # Slower, smaller files
2. Use multi-threading:
# Use 4 threads for compression
qsave(obj,"parallel_save.qs", nthreads =4)
qs_save(obj,"parallel_save.qs2", nthreads=4)
3. Reduce memory footprint (partial loading): While qs/qs2 dramatically speed up saving/loading R objects, they don't support partial loading the way Python tools do. That is, when you load a qs file, the entire object is still read into memory. If you need to reduce memory usage, the current best practice is to use the BPCells package to keep the largest matrices from your Seurat object on disk, loading only the portions needed for computation into memory. I may cover the specifics of this approach in a future post. (From my own testing, BPCells and the qs package work great together!)
What other single-cell power tips are you interested in? Feel free to share and discuss in the comments!
- End -
Originally posted on WeChat Official Account: bioinfo_studyroom